Chapter 31 - PostgreSQL Operations, Backups, and Disaster Recovery
When PostgreSQL is the only mandatory infrastructure service, its reliability plan is the platform reliability plan. Backups that have never been restored are not evidence.
Sizing from workload
Estimate separately:
- accepted points per second and burst rate;
- rows and bytes per day;
- WAL generated per day;
- current-state updates per second;
- history query concurrency;
- worker write and read load;
- geospatial index size;
- backup window and restore bandwidth;
- retention and partition count.
Disk latency and sustained write throughput often matter more than nominal CPU. Reserve free space for WAL spikes, index creation, vacuum, and restore operations.
Configuration
Tune after measuring. Areas to review include:
shared_buffers;- effective cache estimate;
- WAL size and checkpoint cadence;
- autovacuum thresholds for high-volume tables;
- work memory for controlled reporting roles;
- parallel query behavior;
- connection limit and pool budgets;
- statement and lock timeouts;
- logging of slow statements and checkpoints.
Avoid copying a generic tuning file without understanding host memory and workload.
High availability
A portable HA design can use PostgreSQL streaming replication to a standby. Automated failover adds coordination complexity and risk of split brain. Choose manual or automated failover based on the team's operating capability and recovery objective.
The application uses a stable database endpoint or controlled configuration change. It must handle connection loss, reject unsafe writes during transition, and recover pools.
A standby is not a backup. Replication repeats accidental deletion and corruption.
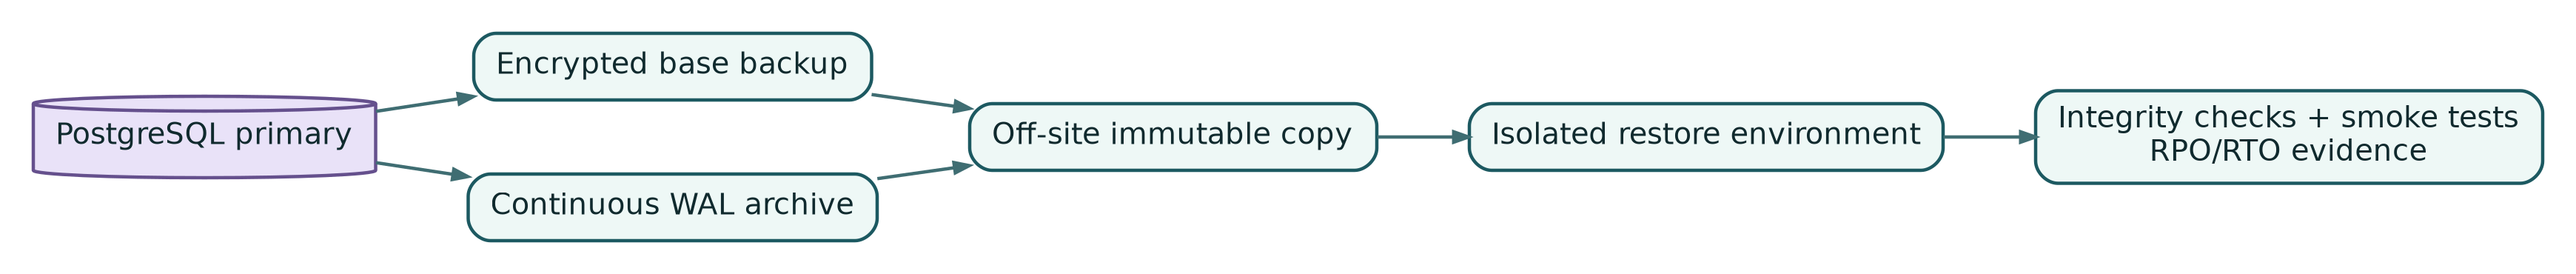
Backup components
A recoverable backup strategy includes:
- periodic consistent base backups;
- continuous WAL archiving;
- encrypted off-site copies;
- retention across daily, weekly, and monthly windows as required;
- checksums and manifest verification;
- documented key recovery;
- application files and configuration backups;
- schema and release metadata.
Use established PostgreSQL tooling such as pg_basebackup or a dedicated backup tool after operational review. The exact tool is less important than restore evidence.
Point-in-time recovery
PITR restores a base backup and replays WAL to a target time or transaction. A drill should:
- provision an isolated host or namespace;
- retrieve backup and keys without production shortcuts;
- restore the base backup;
- configure WAL recovery to a target;
- start PostgreSQL;
- verify recovery completion;
- run schema, count, RLS, PostGIS, and application smoke tests;
- measure actual RPO and RTO;
- document failures and improvements;
- destroy sensitive drill data securely.
Backup privacy
Backups contain location and secrets. Protect them with:
- encryption before off-site transfer;
- separate access control;
- immutable or append-only retention where possible;
- key separation;
- access audit;
- expiry and deletion procedures;
- restricted restore environments.
Do not copy production backups to developer laptops for convenience.
Partition maintenance
Operations include:
- creating future partitions;
- checking default-partition use;
- analyzing new partitions;
- monitoring bloat and index growth;
- archiving or dropping expired partitions;
- reindexing only with measured need;
- preventing a maintenance job from saturating I/O.
Retention jobs and backup schedules should not collide with peak ingest periods without capacity evidence.
Migration safety
Before deployment:
- estimate lock behavior;
- test on production-like data volume;
- set lock timeout;
- use concurrent index creation where appropriate;
- backfill in bounded batches;
- expose progress metrics;
- prepare abort and rollback behavior;
- verify old and new application versions.
A migration command should refuse to run against an unexpected environment and should print the exact plan without secrets.
Failure runbooks
Maintain runbooks for:
- database unreachable;
- disk nearly full;
- replication lag;
- standby promotion;
- corrupted index;
- slow query storm;
- autovacuum backlog;
- failed WAL archive;
- failed backup;
- accidental deletion and PITR;
- leaked database credential.
Each runbook names decision authority, safe diagnostics, mitigation, recovery, and post-incident evidence.
Chapter checklist
PostgreSQL operations are credible when:
- sizing includes WAL, indexes, bursts, and restore bandwidth;
- configuration is measured, not copied blindly;
- replication and backup are treated separately;
- base backups and WAL are encrypted off-site;
- restore drills run regularly and measure RPO/RTO;
- partition maintenance is automated and observed;
- migrations are volume-tested and lock-aware;
- common failures have executable runbooks.